Tutorial: Surface Code Sampling with Clifft and Stim
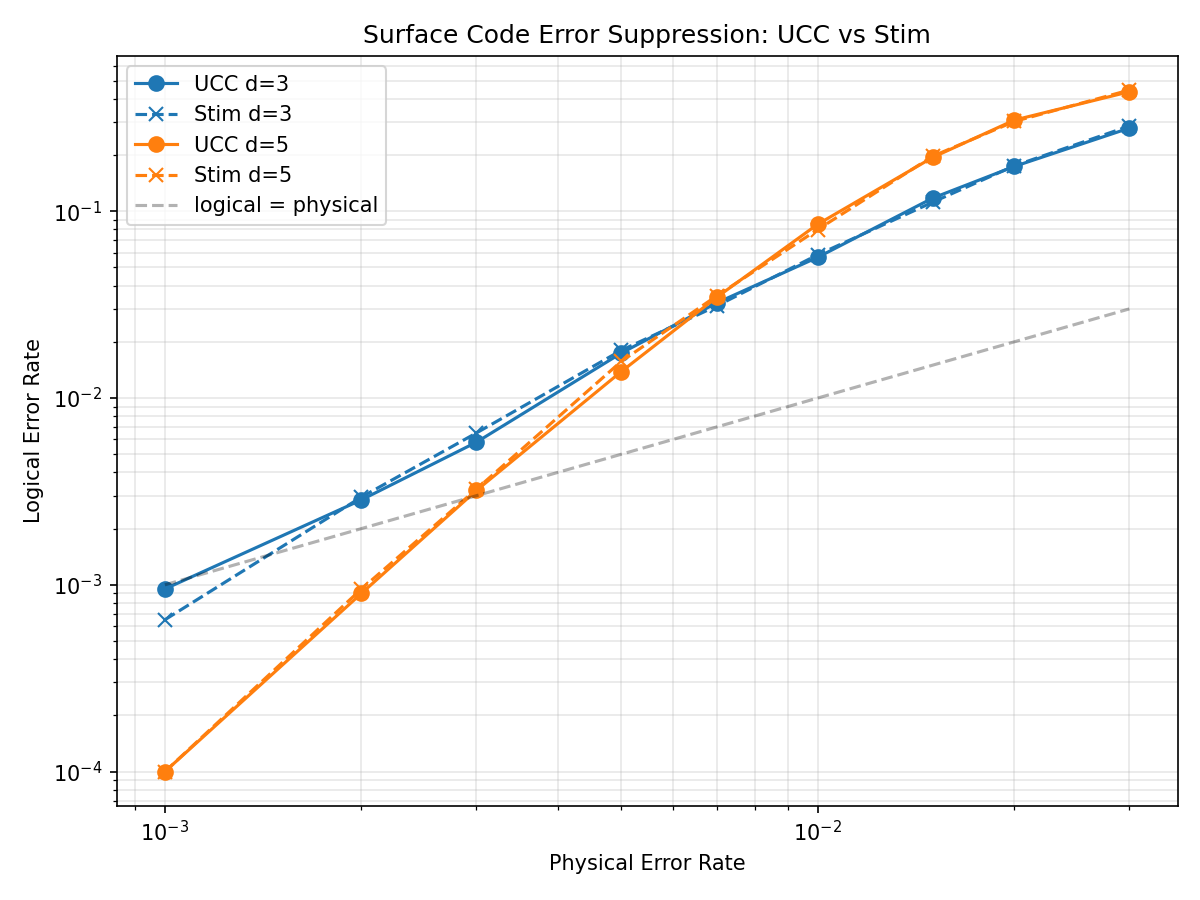
This tutorial demonstrates using Clifft to sample quantum error correction experiments. We reproduce a surface code error suppression plot similar to Stim's getting started notebook, running both Clifft and Stim side-by-side to verify statistical equivalence. Since this is a Clifford-only circuit, Stim is the more specialized tool, but the comparison is useful for checking that both samplers produce the same detector and logical statistics.
We use PyMatching for minimum-weight perfect matching (MWPM) decoding with both samplers.
Pipeline
The experiment follows four steps, executed for both samplers:
- Generate a rotated surface code memory-Z circuit with
stim.Circuit.generated() - Compile the circuit (Clifft:
clifft.compile()with full optimization; Stim:compile_detector_sampler()) - Sample detector and observable data, timing each sampler
- Decode detector syndromes with PyMatching's MWPM decoder and compare logical error rates
Prerequisites
Full Code
import time

import matplotlib.pyplot as plt
import numpy as np
import pymatching
import stim

import clifft


def generate_surface_code_circuit(
    distance: int,
    rounds: int,
    phys_error_rate: float,
) -> stim.Circuit:
    """Generate a rotated surface code memory-Z experiment."""
    return stim.Circuit.generated(
        "surface_code:rotated_memory_z",
        rounds=rounds,
        distance=distance,
        after_clifford_depolarization=phys_error_rate,
        after_reset_flip_probability=phys_error_rate,
        before_measure_flip_probability=phys_error_rate,
        before_round_data_depolarization=phys_error_rate,
    )


def decode_logical_error_rate(
    det: np.ndarray,
    obs: np.ndarray,
    circuit: stim.Circuit,
) -> float:
    """Decode detector syndromes and compute the logical error rate."""
    dem = circuit.detector_error_model(decompose_errors=True)
    matching = pymatching.Matching.from_detector_error_model(dem)
    predictions = matching.decode_batch(det)
    num_errors = int(np.sum(predictions[:, 0] ^ obs[:, 0]))
    return num_errors / det.shape[0]


def run_clifft(
    circuit: stim.Circuit, shots: int
) -> tuple[float, float, float]:
    """Compile and sample with Clifft.

    Returns (logical_error_rate, compile_seconds, sample_seconds).
    """
    stim_text = str(circuit)
    hir_pm = clifft.default_hir_pass_manager()
    t0 = time.perf_counter()
    prog = clifft.compile(stim_text, hir_passes=hir_pm)
    compile_s = time.perf_counter() - t0

    t0 = time.perf_counter()
    result = clifft.sample(prog, shots)
    sample_s = time.perf_counter() - t0

    logical_err = decode_logical_error_rate(result.detectors, result.observables, circuit)
    return logical_err, compile_s, sample_s


def run_stim(
    circuit: stim.Circuit, shots: int
) -> tuple[float, float, float]:
    """Compile and sample with Stim.

    Returns (logical_error_rate, compile_seconds, sample_seconds).
    """
    t0 = time.perf_counter()
    sampler = circuit.compile_detector_sampler()
    compile_s = time.perf_counter() - t0

    t0 = time.perf_counter()
    det, obs = sampler.sample(shots, separate_observables=True)
    sample_s = time.perf_counter() - t0

    logical_err = decode_logical_error_rate(det, obs, circuit)
    return logical_err, compile_s, sample_s


# -- Experiment parameters --
distances = [3, 5]
phys_error_rates = [
    0.001, 0.002, 0.003, 0.005, 0.007, 0.01, 0.015, 0.02, 0.03,
]
shots = 20_000

# -- Collect data --
clifft_results: dict[int, list[float]] = {}
stim_results: dict[int, list[float]] = {}
timing_rows: list[tuple[int, float, float, float, float, float]] = []

for d in distances:
    clifft_results[d] = []
    stim_results[d] = []
    for p in phys_error_rates:
        circuit = generate_surface_code_circuit(d, rounds=d, phys_error_rate=p)

        clifft_err, clifft_comp, clifft_samp = run_clifft(circuit, shots)
        stim_err, stim_comp, stim_samp = run_stim(circuit, shots)

        clifft_results[d].append(clifft_err)
        stim_results[d].append(stim_err)
        timing_rows.append((d, p, clifft_comp, clifft_samp, stim_comp, stim_samp))

        print(
            f"d={d}  p={p:.4f}  "
            f"Clifft={clifft_err:.5f} ({clifft_comp*1e3:.1f}ms + {clifft_samp:.3f}s)  "
            f"Stim={stim_err:.5f} ({stim_comp*1e3:.1f}ms + {stim_samp:.3f}s)"
        )

# -- Timing summary --
print("\n--- Timing Summary ---")
print(
    f"{'d':>3} {'p':>7} "
    f"{'Clifft compile':>13} {'Clifft sample':>12} "
    f"{'Stim compile':>13} {'Stim sample':>12}"
)
for d, p, uc, us, sc, ss in timing_rows:
    print(
        f"{d:>3} {p:>7.4f} "
        f"{uc*1e3:>11.1f}ms {us:>10.3f}s "
        f"{sc*1e3:>11.1f}ms {ss:>10.3f}s"
    )

# -- Plot --
fig, ax = plt.subplots(figsize=(8, 6))
colors = ["#1f77b4", "#ff7f0e"]
for i, d in enumerate(distances):
    ax.plot(
        phys_error_rates, clifft_results[d],
        "o-", color=colors[i], label=f"Clifft d={d}", markersize=7,
    )
    ax.plot(
        phys_error_rates, stim_results[d],
        "x--", color=colors[i], label=f"Stim d={d}", markersize=7,
    )

ax.plot(
    phys_error_rates, phys_error_rates,
    "k--", alpha=0.3, label="logical = physical",
)
ax.set_xscale("log")
ax.set_yscale("log")
ax.set_xlabel("Physical Error Rate")
ax.set_ylabel("Logical Error Rate")
ax.set_title("Surface Code Error Suppression: Clifft vs Stim")
ax.legend()
ax.grid(True, which="both", alpha=0.3)
plt.tight_layout()
plt.savefig("surface_code.png", dpi=150)
plt.show()
How It Works
Circuit Generation
Stim generates the full noisy surface code circuit including:
- Data qubit initialization and measurement
- Stabilizer measurement rounds with ancilla qubits
- Depolarizing noise after Clifford gates, reset, and measurement
DETECTORannotations marking parity checksOBSERVABLE_INCLUDEannotations for logical observable tracking
For distance \(d\), the rotated surface code has \(d^2\) data qubits and \((d^2 - 1)/2\) ancilla qubits. Stim allocates qubit indices on a 2D coordinate grid, so the total qubit index count is higher: distance 3 uses 26 qubit indices, and distance 5 uses 64.
Clifft Compilation & Sampling
clifft.compile() accepts the full Stim circuit text — including REPEAT blocks, noise channels, DETECTOR and OBSERVABLE_INCLUDE annotations. In this tutorial, we use the full optimization pipeline:
- HIR passes (
clifft.default_hir_pass_manager()): Peephole fusion on the Heisenberg IR - Executable-plan lowering: active-coordinate planning, expression preparation, and kernel selection
The compiled program is then sampled with clifft.sample(), which returns a SampleResult object:
- measurements: raw measurement outcomes
- detectors: detector values (syndrome bits)
- observables: logical observable outcomes
Stim Compilation & Sampling
Stim's compile_detector_sampler() compiles the circuit into an optimized Clifford-frame simulator. Like Clifft, Stim resolves deterministic Clifford impacts at compile time. Because Stim is restricted to Clifford+noise circuits, it never maintains an active state vector and can vectorize sampling across many shots simultaneously using SIMD instructions, making it extremely fast for this class of circuits.
Decoding
Both samplers produce detector and observable arrays in the same format. PyMatching constructs a matching graph from Stim's detector error model and performs MWPM decoding on the detector syndromes. The logical error rate is the fraction of shots where the decoder's prediction disagrees with the actual observable value.
Results
The plot confirms that Clifft and Stim produce statistically equivalent logical error rates across all tested distances and physical error rates. Both curves overlap closely, with only shot-noise fluctuations between them.
The classic threshold behavior of the surface code is visible:
- Below threshold (~\(p = 0.005\)): increasing distance \(d\) exponentially suppresses logical errors. At \(p = 0.001\), distance 5 achieves roughly \(10\times\) lower logical error rate than distance 3.
- Above threshold: larger codes perform worse because they have more opportunities for errors to accumulate.
- The crossover point is the threshold of the surface code under this noise model.
Performance Comparison
The script prints compilation and sampling times for the local run, but those numbers depend on the installed versions, hardware, and execution target. Stim is expected to be faster here: because it is Clifford-only, it never needs an active statevector array and can pack work from many shots into SIMD instructions. The key result of this tutorial is that the logical error rates agree while Clifft's compiler and sampler also generalize beyond stabilizer circuits.